
There is a part of the data processing world that rarely gets the attention it deserves.
It isn’t glamorous. It doesn’t generate exciting dashboards. It probably won’t feature prominently in an AI strategy presentation.
But get it wrong and virtually everything that follows can go wrong.
Name and address parsing.
At The Software Bureau, we believe accurate parsing is the bedrock of batch data processing. Whether the objective is address matching, deduplication, sorting, indexing, suppression, enrichment or the creation of a Single Customer View (SCV), it all starts with understanding exactly what is contained within a name and address record.
And that is considerably more complicated than it sounds.
What exactly is parsing?
At its simplest, parsing is the process of taking unstructured or semi-structured name and address information and breaking it down into its individual components.
But a UK contact name and address can contain up to 159 individual parsed elements.
Think about that for a moment.
House numbers, flat numbers, building names, sub-building information, thoroughfares, dependent thoroughfares, localities, post towns, counties, postcodes, organisation names, personal names, titles and much more can potentially form part of a single contact record.
And those elements don’t necessarily arrive in a nice, clean, predictable format.
Real-world data is messy.
Names are entered differently. Addresses are abbreviated. Fields are concatenated. Information appears in the wrong place. Punctuation comes and goes. Organisations are recorded as individuals and individuals are recorded as organisations.
The job of a parsing engine is to make sense of all of this.
Parsing comes before matching
This is the really important bit.
You cannot reliably match data that you haven’t accurately understood.
It is tempting to think that the Royal Mail Postcode Address File (PAF) solves the address problem.
PAF is an incredibly valuable reference dataset and is fundamental to address standardisation and validation.
But PAF on its own is not a magic wand.
If the incoming address hasn’t first been accurately parsed, the process of matching that record against PAF can become a relatively blunt instrument.
Consider an address containing a flat number, building name, organisation name and a complex street structure. If those components haven’t been correctly identified, how can a matching process know which parts of the address are significant, and which aren’t?
The quality of the match is fundamentally dependent upon the quality of the data presented to it.
Parse first. Match second.
It sounds obvious.
It isn’t always done properly.
28 years of continuous refinement
The Software Bureau (tSB) was founded in 1998.
For almost three decades, we have been developing and refining software designed to process names and addresses at scale.
At the heart of our applications sits a parsing engine that has been continuously refined through years of development, testing and real-world processing.
And importantly, that refinement hasn’t happened in isolation.
Our clients have played a huge part.
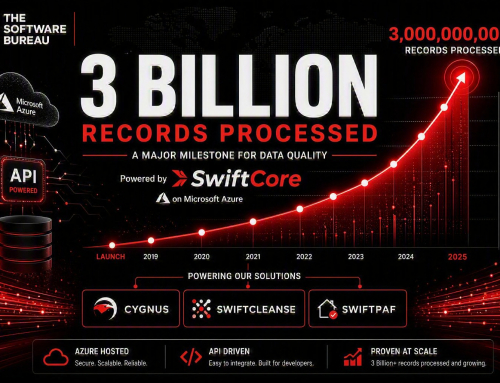
Between them, tSB clients process hundreds of billions of name and address records every year through our software. That volume provides an extraordinary amount of real-world feedback.
Every unusual address structure, unexpected data combination, obscure abbreviation and edge case provides another opportunity to improve the logic.
Over 28 years, those improvements add up.
The result isn’t simply a parser.
It is an engine containing decades of accumulated knowledge about how people and organisations actually record names and addresses.
Logic, validation and experience
Our parsing engine combines sophisticated parsing logic with extensive validation tables designed to help determine what individual pieces of information actually represent.
Because context matters.
A sequence of characters could be a street name, a building name, an organisation, a locality or something else entirely. The engine needs to make an informed decision based upon the data surrounding it.
This is where decades of refinement become important.
The objective isn’t merely to split a string into pieces.
It is to understand the data sufficiently well that those pieces can subsequently be used intelligently.
That distinction is critical when the next stage is matching, deduplication, indexing or building a Single Customer View.
And then there is the profanity problem…
There is another little feature sitting inside our parsing engine that has generated some rather entertaining results over the years.
Profanity screening.
Why?
Because data doesn’t always contain what you expect it to contain.
Our screening logic helps identify potentially spurious data within names and addresses, including obscenities and words associated with death or other inappropriate content.
And yes, over the years it has caught some absolute howlers.
Imagine a perfectly respectable customer database containing a field that suddenly reads something along the lines of:
“John Smith – [Daft Old Git] – London – SW1…”
Or an address field containing language that clearly had absolutely no business being there.
We’ve seen obscenities accidentally imported into customer databases, inappropriate words embedded within otherwise legitimate data, and even references to someone’s death appearing where perfectly normal customer information should have been.
Sometimes the cause is obvious. A data entry error. A corrupted field. An application allowing free-text input where it really shouldn’t. A badly concatenated record.
Sometimes it’s considerably harder to explain.
That’s why profanity screening isn’t simply a novelty feature.
It’s another layer of data quality control.
It can flag records that deserve further investigation before they are passed into matching, enrichment, mailing or downstream customer databases.
And occasionally, it gives the people reviewing the data a very good laugh.
The need for speed
At tSB, our parsing engine doesn’t just need to be accurate.
It needs to be mind-blowingly quick.
When you’re processing millions, tens of millions or hundreds of millions of records, even a tiny inefficiency can become a very large problem.
Batch processing environments demand throughput.
Our clients aren’t interested in an engine that can parse an address beautifully if it takes all afternoon to process the file.
Accuracy and performance have to coexist.
That is one of the reasons our parsing technology has evolved continuously alongside the enormous processing volumes generated by our clients.
The overlooked foundation of batch processing
Parsing sits underneath far more than address matching.
Think about what happens during a typical batch processing operation.
A file arrives.
Names and addresses need to be interpreted.
The individual components need to be identified.
Records need to be validated and standardised.
They may then need to be matched against reference data.
Duplicates may need to be identified.
Records may need to be sorted.
Indexes and keys may need to be created.
Additional data may need to be appended.
And increasingly, records need to be matched against information held in completely different systems.
Every one of those processes benefits from having the underlying name and address data correctly understood.
Parsing is therefore not simply another stage of data processing. It is the foundation upon which many of the subsequent stages depend.
Parsing and the Single Customer View
This becomes particularly important when we look at the next generation of data processing: Single Customer View.
An SCV is only as good as the records that go into it.
If the same customer appears in multiple databases, systems or files, the challenge is to determine that those records represent the same individual or household.
That requires reliable matching.
And reliable matching requires consistent, meaningful data.
Which brings us right back to parsing.
We are currently in the process of exposing our parsing engine to the world of Single Customer View processing, with an additional layer of matchkeys generated from the parsed data.
The objective is straightforward:
Understand the record. Extract the meaningful components. Generate intelligent matchkeys. Then use those matchkeys to help identify relationships between records.
Rather than treating a name and address as one long string of characters, the engine understands its constituent parts and can use that intelligence to support more sophisticated matching.
That has significant potential for organisations attempting to build a genuinely accurate SCV from multiple sources.
The real test: can your data create a Golden Record?
This is where parsing becomes particularly important for Single Customer View.
Many organisations are trying to create the elusive “Golden Record”: a single, trusted representation of a customer assembled from multiple systems, databases and historical files.
But if you’re struggling to achieve the match rates you expected, the instinct can be to look immediately at the matching algorithm.
Perhaps the problem is actually further upstream.
What if the problem isn’t your matching technology? What if it’s the way your data is being parsed before it ever reaches the matching engine?
If names and addresses aren’t being accurately understood and broken down into their constituent elements, your matching process is starting with a disadvantage.
And no amount of clever matching logic can completely compensate for poor foundations.
That’s why we believe parsing deserves much more attention in the SCV conversation.
Before you chase the Golden Record, look at the foundations
If you’re working on a Single Customer View and struggling with match rates…
If you’re spending too much time trying to reconcile records that should obviously belong to the same customer…
If you’re generating too many false positives or false negatives…
Or if you’re still chasing that elusive Golden Record…
Perhaps it’s time to look one step further back in the process.
What parsing technology sits underneath your matching engine?
Because before you can match a customer, you need to understand the data.
And before you can create a Golden Record, you need to get the building blocks right.
At The Software Bureau, we’re taking 28 years of parsing experience and applying it directly to the Single Customer View challenge.
Our next-generation SCV capability is being built around our proven parsing engine, with a new layer of intelligent matchkeys generated from the parsed data to help identify and connect customer records across disparate datasets.
We’re currently putting the finishing touches to this technology and preparing it for launch.
Struggling with your SCV match rates?
Let’s talk.
If you’re working on a Single Customer View project and aren’t achieving the match rates you expected, we’d be interested in understanding what you’re trying to achieve and how your existing data processing works.
You may not need a better matching algorithm.
You may simply need to start with better parsing.
Watch this space for more information about our new SCV processing capability and the expected launch date.
The Software Bureau | 28 years of making sense of names and addresses.