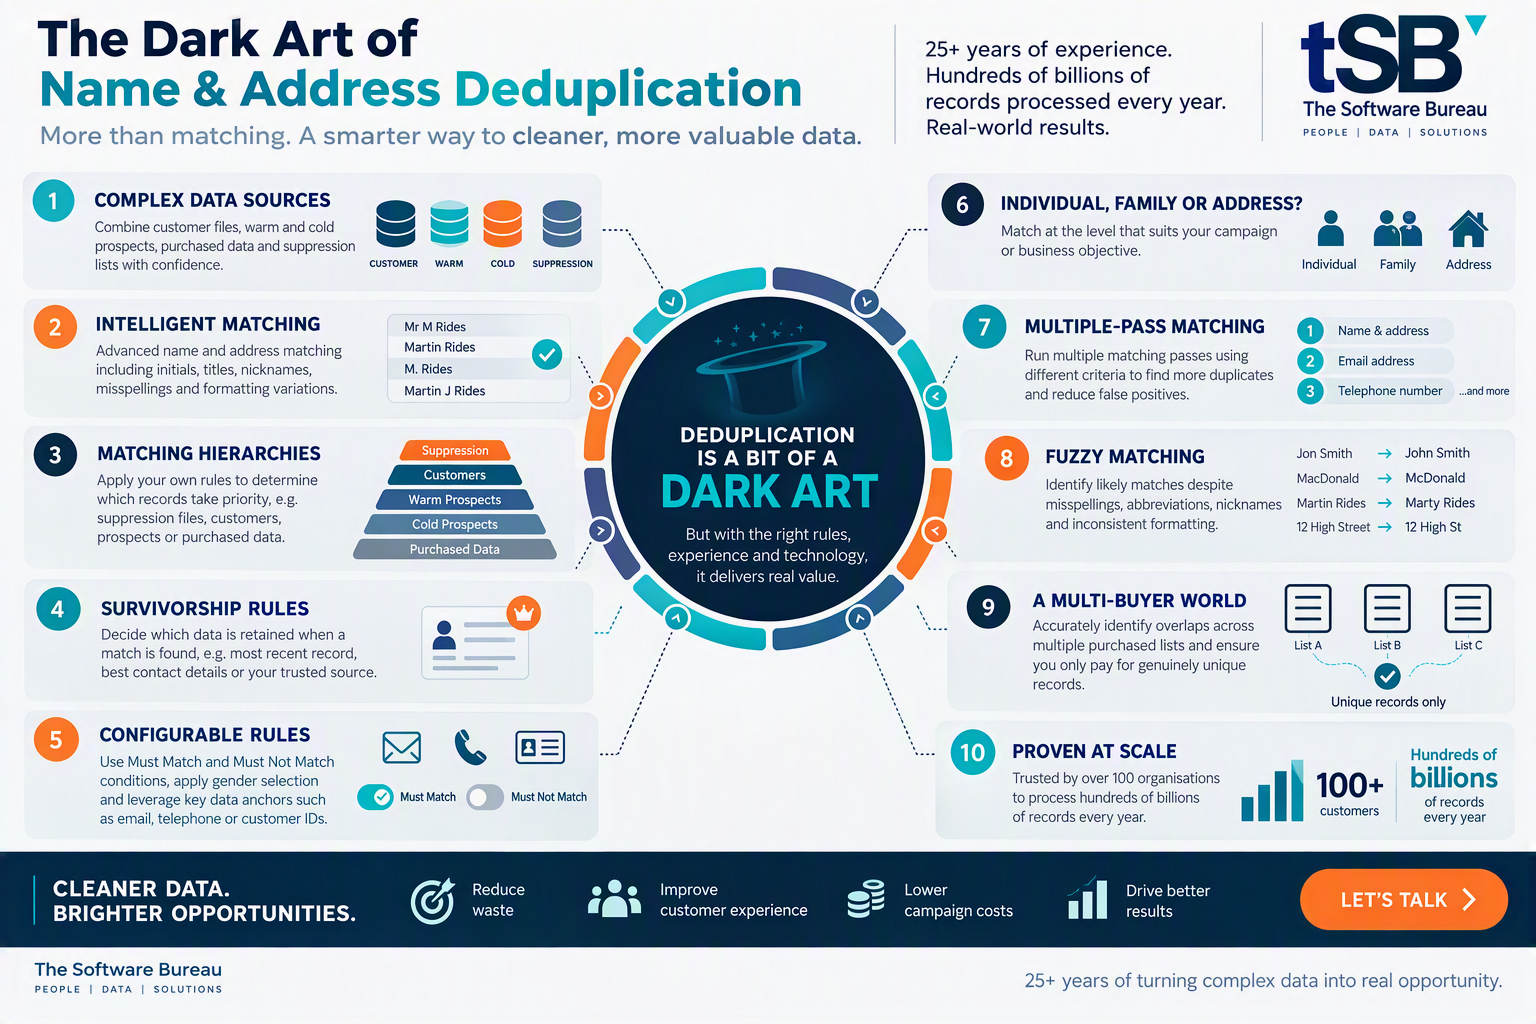
The Dark Art of Name & Address Deduplication

By |2026-10-23T18:50:37+00:00October 23rd, 2026|

Why 25 years of experience still matters when everyone thinks matching records is easy. At first glance, deduplication seems straightforward. Compare two records. Decide whether they match. Remove the duplicate. Job done. If only it were that simple. At The Software Bureau, we've been immersed in the world of data matching and deduplication since the company was formed in 2000. In fact, our founders were building sophisticated deduplication solutions even before then. Over the past 25+ years we've helped organisations tackle some of the most complex matching challenges imaginable, processing hundreds of billions of records through our software every year. Today, SwiftDedupe helps organisations configure complex matching strategies incorporating individual, family and address-level matching, suppression hierarchies, survivorship rules, fuzzy matching [...]
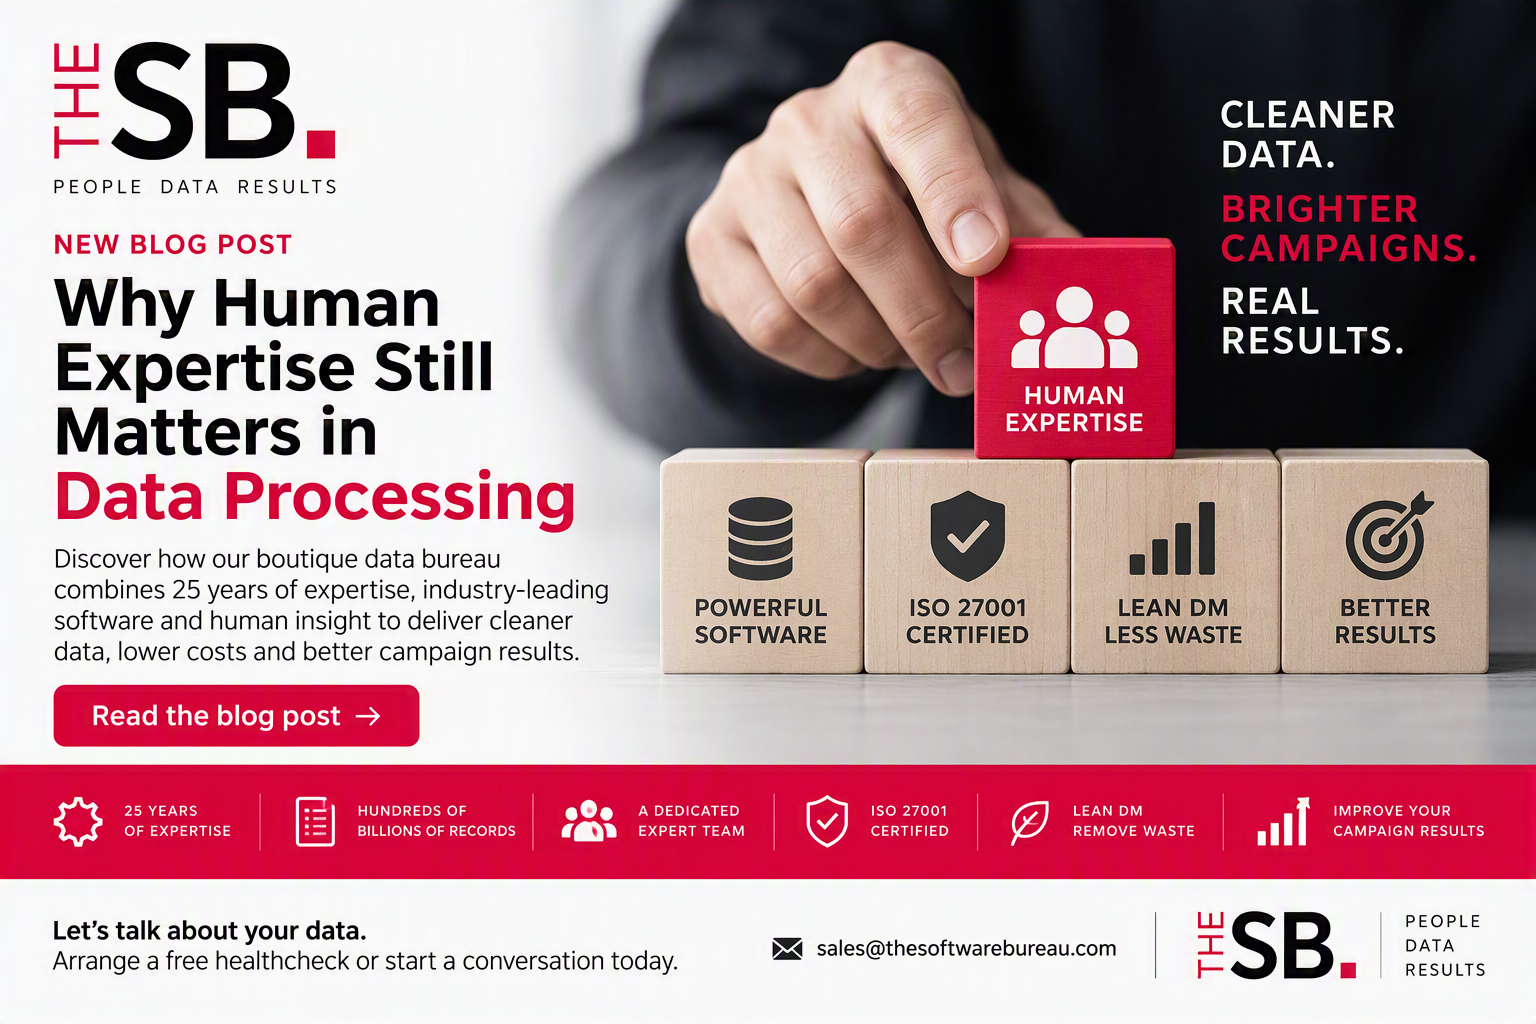
Why Human Expertise Still Matters in Data Processing

By |2026-10-14T11:22:03+00:00October 14th, 2026|

In a world increasingly driven by automation, APIs and self-service platforms, it's easy to assume that data processing has become a commodity. Upload a file, press a button, and let the software do the work. The reality is very different. Data quality remains one of the biggest challenges facing organisations today. Customer data is often collected from multiple sources, stored in different formats, and maintained by different teams over many years. Every dataset has its own quirks, inconsistencies and hidden issues. That is why experience, expertise and human insight still play a critical role in achieving the best possible outcomes. At The Software Bureau, we've built a boutique data bureau service that combines industry-leading software with something far more valuable: [...]

The Software Bureau vs matchIT

By |2026-09-28T13:05:11+00:00September 28th, 2026|

The UK on-premise and cloud data quality alternative. A practical comparison for UK data teams reviewing alternatives as matchIT support winds down. Quick summary If you’re running matchIT today, whether that’s the desktop tool, the SQL Server integration or matchIT Web, and you’re weighing what comes next, this is a practical comparison of what a move to The Software Bureau looks like. Dozens of organisations have made the switch from matchIT to The Software Bureau over the years, and with an increasing number of enquiries from matchIT customers we put together the following comprehensive guide to help explain the differences. Short version: matchIT was built as a technical matching engine for UK data teams and became a [...]

Unlocking Ultimate Data Hygiene Flexibility: Why You Shouldn’t Have to Compromise

By |2026-08-25T08:40:19+00:00August 25th, 2026|

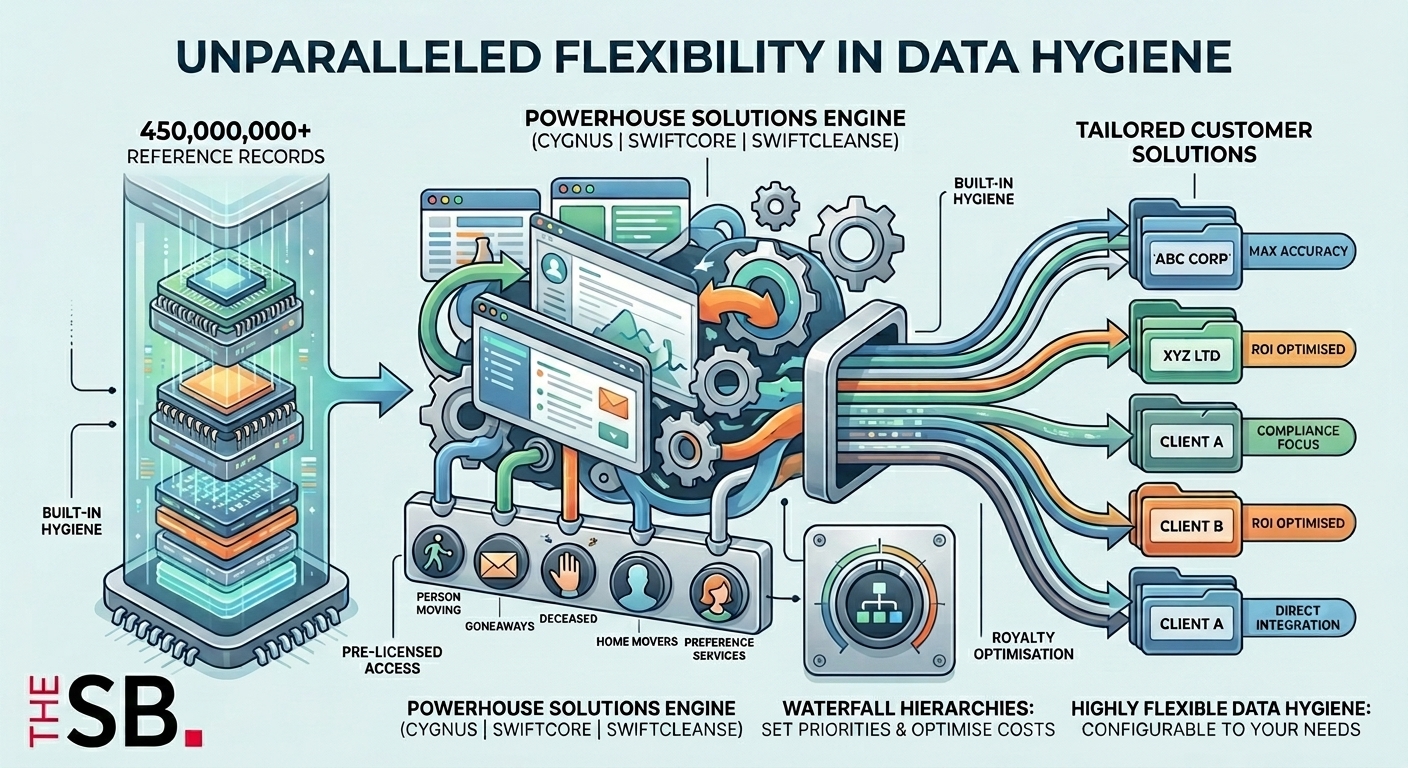
Data hygiene is often treated as a final administrative check box for direct marketing, but it is actually one of the core drivers of enterprise data accuracy, campaign ROI, and regulatory compliance. Inaccurate customer data spreads far beyond wasted printing and postage costs. When records are outdated, uncleaned, or duplicate, the impact ripple across your entire business: analytics models fail, customer insights become skewed, and strategic decisions are built on faulty foundations. At the operational level, reaching out to consumers who have moved or passed away damages brand trust and risks non-compliance under GDPR. Yet, for many data processors and database operations, data hygiene has traditionally been a clunky, multi-step chore. From exporting files to third-party providers and managing individual [...]

You Can’t Match What You Can’t Understand: Why Name & Address Parsing Is the Bedrock of Data Processing

By |2026-08-24T11:08:55+00:00August 24th, 2026|

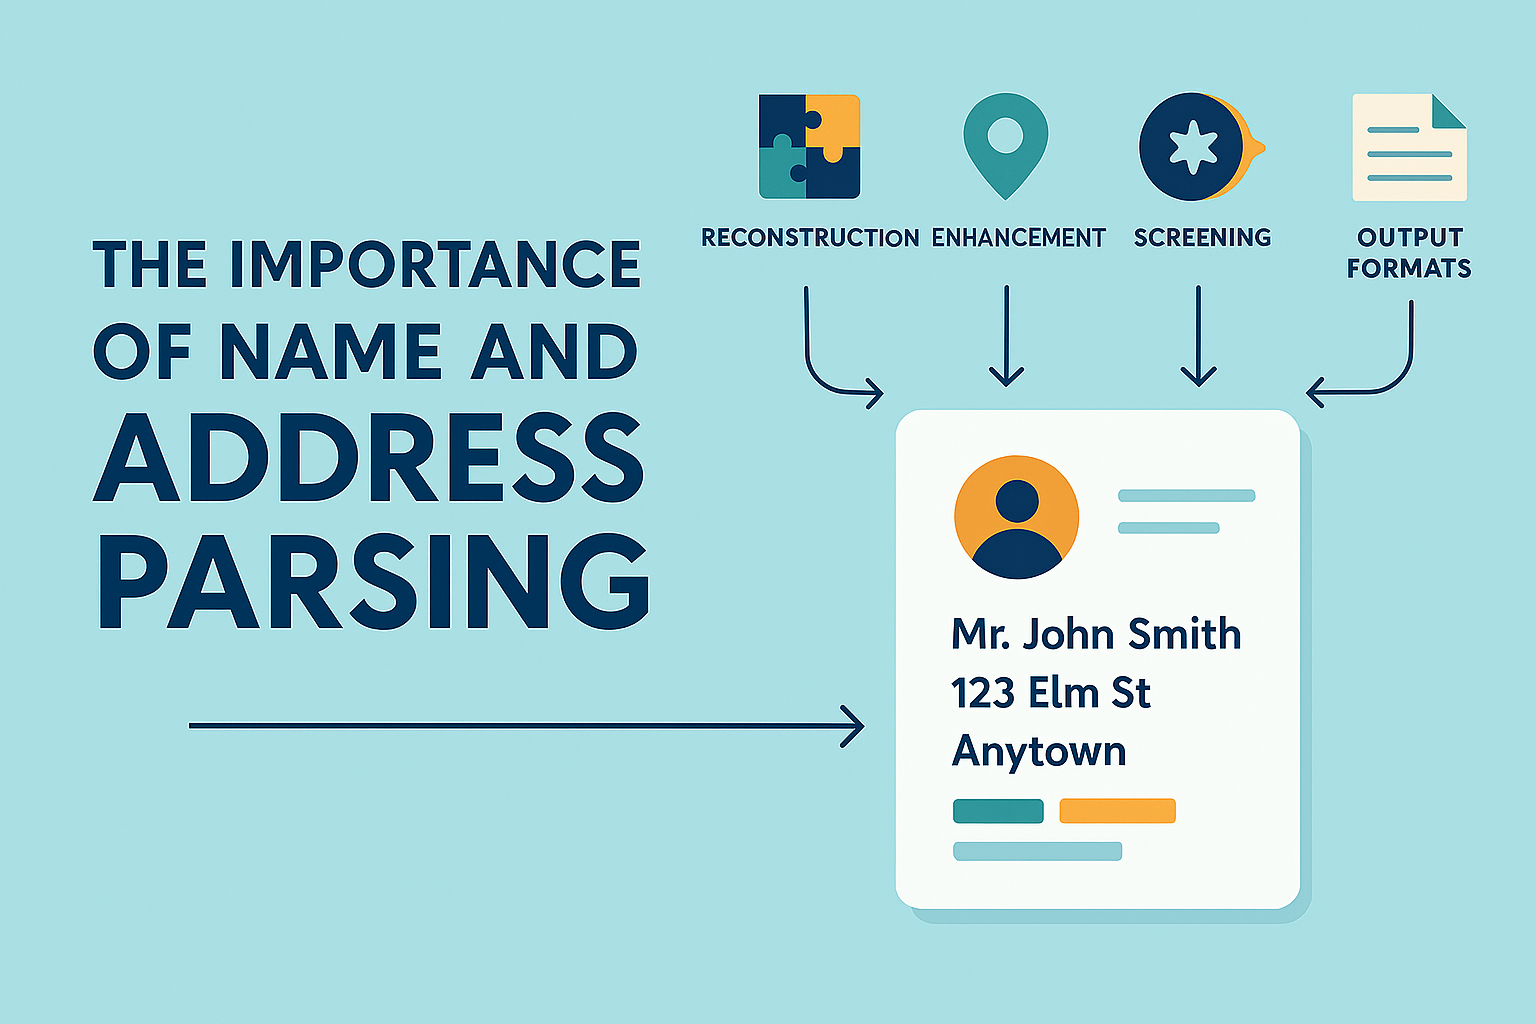
There is a part of the data processing world that rarely gets the attention it deserves. It isn't glamorous. It doesn't generate exciting dashboards. It probably won't feature prominently in an AI strategy presentation. But get it wrong and virtually everything that follows can go wrong. Name and address parsing. At The Software Bureau, we believe accurate parsing is the bedrock of batch data processing. Whether the objective is address matching, deduplication, sorting, indexing, suppression, enrichment or the creation of a Single Customer View (SCV), it all starts with understanding exactly what is contained within a name and address record. And that is considerably more complicated than it sounds. What exactly is parsing? At its simplest, parsing is the process [...]

The History of Royal Mail’s Postcode Address File (PAF): A Timeline of Addressing Evolution

By |2026-06-10T09:27:23+00:00June 10th, 2026|

The Royal Mail’s Postcode Address File (PAF) is one of the most important yet often overlooked datasets in the UK. It underpins everything from mail delivery to e-commerce checkouts, credit checks, and emergency response systems. But PAF didn’t appear overnight. It evolved over decades alongside changes in addressing, technology, and society. This post explores the history and evolution of PAF, from the early days of postal districts to the digital infrastructure we rely on today. Before PAF: The Foundations of Modern Addressing (Pre-1970) 1850s–1910s: Postal districts and sorting efficiency Major cities such as London began using postal districts (e.g. “EC” or “SW”) in the mid-19th century. These were introduced to improve sorting efficiency as urban populations grew rapidly. However, outside [...]

Why Regular Data Cleansing Is Essential for Modern Brands

By |2026-05-21T11:31:10+00:00May 21st, 2026|

Customer data is one of the most valuable assets any organisation owns. It powers marketing, customer experience, compliance and revenue growth. Yet without ongoing maintenance, even the strongest datasets deteriorate rapidly. People move home. People pass away. Contact details change. And when your data is out of date, the impact is immediate and costly. The Real Cost of Dirty Data Data decay is not a slow problem. It is constant and compounding. Without regular cleansing, organisations face: Wasted Budget Marketing campaigns targeting inaccurate or outdated records result in: Unnecessary print and postage costs Reduced response rates Lower overall ROI Reputational Damage Contacting individuals who have moved or, worse, deceased individuals can create deeply negative customer experiences and erode brand trust. [...]

Why Name and Address Parsing Is the Foundation of Every Data Quality Success

By |2026-05-11T14:47:09+00:00May 11th, 2026|

What is the single most important capability behind every effective name and address solution? Accurate parsing. Before data can be enhanced, cleansed, screened, sorted or reformatted, it must first be understood. Name and address parsing is the process that makes that understanding possible, transforming raw text into structured, reliable components that software can act on with confidence. At The Software Bureau, parsing is not a feature. It is the foundation. Parsing: the invisible engine of data quality Every contact record starts life as unstructured data. Names arrive in countless formats. Addresses vary by country, convention, abbreviation and free‑form input. Titles, suffixes, building names, sub‑premises and delivery points are often mixed together in ways that defy simple rules. Without accurate parsing, [...]

Why Most Address Validation Tools Cannot Handle Large Direct Mail Databases

By |2026-03-11T11:45:42+00:00March 11th, 2026|

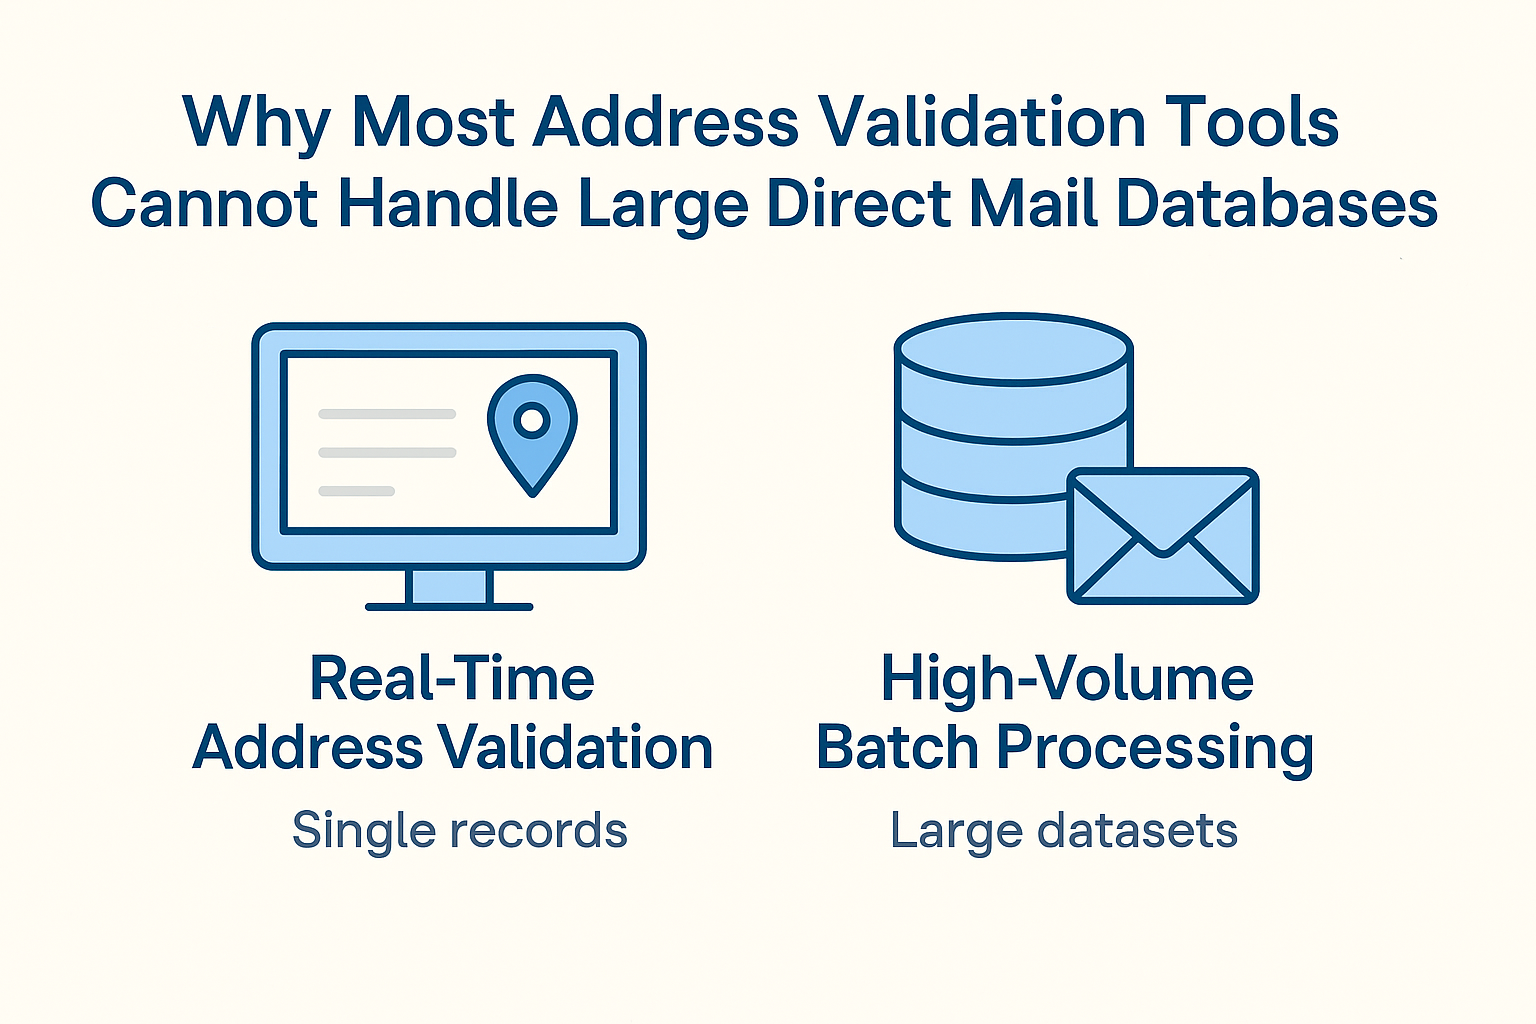
In data marketing, scale determines everything. Validating a single address on a web form is fundamentally different from processing tens or hundreds of millions of customer records for a direct mail campaign. Many organisations assume that the same address validation tools can support both scenarios. They cannot. The gap between real-time address validation and industrial-scale batch processing is significant. Misunderstanding that difference often results in long processing times, inefficient workflows and delays in direct mail production. This article explains why large-scale data processing requires specialist software and how The Software Bureau supports these high-volume environments. Real-Time Address Validation vs High-Volume Batch Processing Most modern address validation services are designed for real-time usage. A typical example is a consumer entering an [...]

Why Processing Customer Data Against Change of Address Files is Crucial for Business Success

By |2026-01-14T12:45:08+00:00January 14th, 2026|

Every year, UK businesses waste £1 billion on mistargeted mailings: sending communications to people who have moved or even passed away. Beyond the financial cost, this erodes brand reputation and risks GDPR non-compliance. With 3.5 million households moving annually and 548,000 deaths each year, customer data decays at an alarming rate. This is why processing your data against Change of Address (COA) datasets is not just best practice; it is essential. What Are COA Data Sets? Change of Address files, such as Royal Mail’s National Change of Address (NCOA) and Experian’s Absolute Contacts, identify when a person has moved and provide their new address. These datasets allow businesses to: Suppress goneaways (people who have moved and not informed you). Update [...]

Go to Top